Data
PDF → CSV Converter
High-accuracy table extraction with a 3-layer OCR stack.
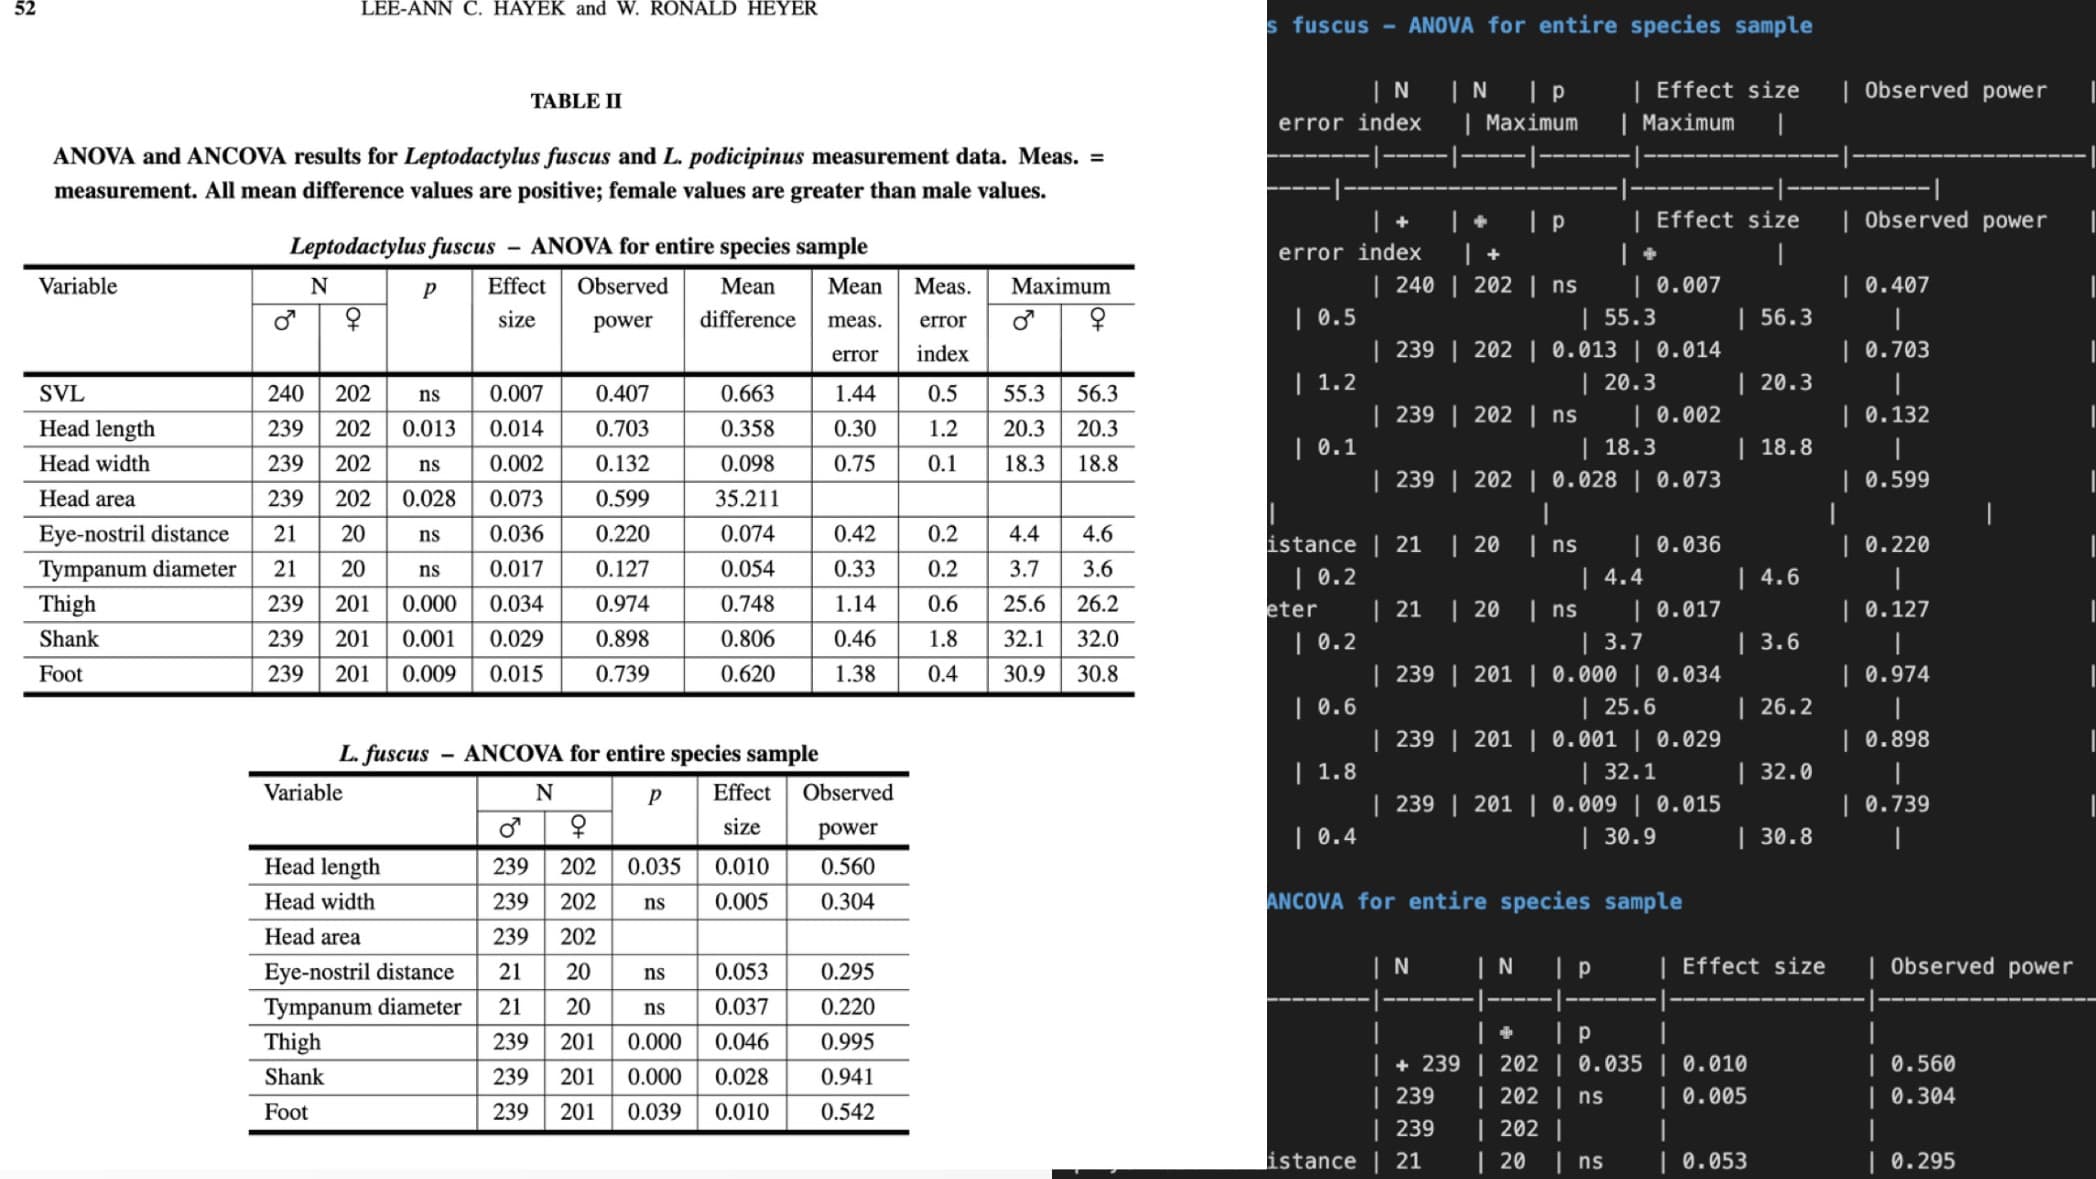
A high-accuracy PDF-to-CSV conversion pipeline in Python that extracts every table into separate CSV files, generates a full-document text file, and outputs structural metadata (table outlines, dimensions, formatting), robust across document layouts. Built with Docling, PyMuPDF, Pandas, and a 3-layer OCR stack.
PythonPandasPyMuPDFDoclingOCR
How it works
Documents flow through structure analysis, table detection, OCR with fallback layers, and finally CSV generation with metadata preservation.
The 3-layer OCR stack (Tesseract → RapidOCR → a custom layer for edge cases) tries progressively more specialized engines, so the system handles varying quality, fonts, and layouts.
Key features
- Multi-table extraction from a single PDF
- Automatic table detection and boundary recognition
- Structural metadata generation (dimensions, formatting)
- Full-document text extraction
Use cases
- Financial document processing
- Research paper data extraction
- Report automation and data migration
- Document digitization workflows